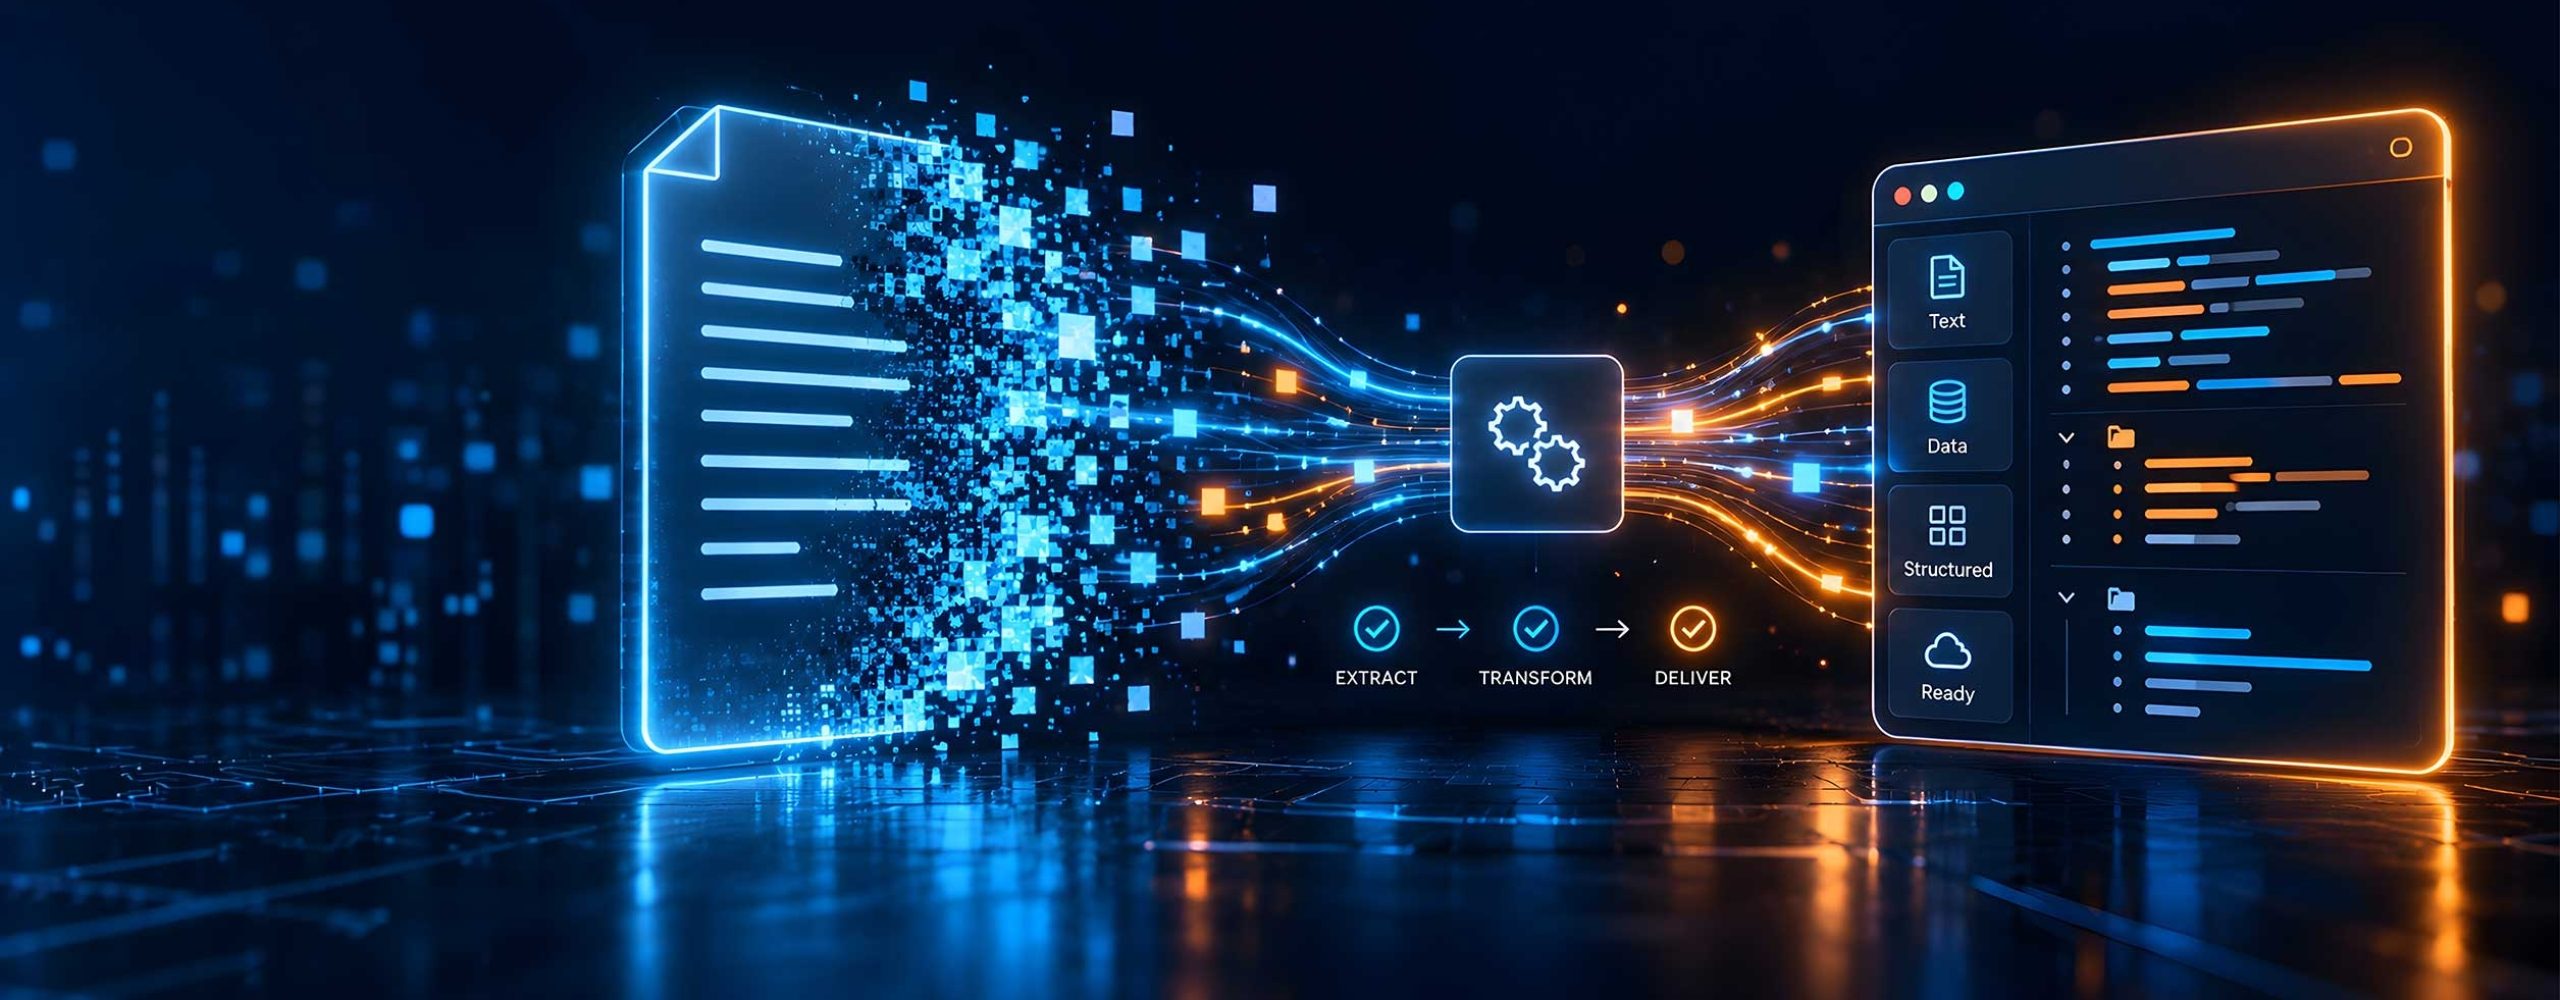
The ETL process consists of three key steps: Extract (E), Transform (T), and Load (L). This proven IT method allows data to be efficiently extracted from a wide variety of sources, processed as needed, and made available in a central system for further use.
Especially in modern companies and organizations, relevant data comes from a variety of sources—ranging from database management systems and external interfaces to files and cloud applications. To make all this diverse information usable, the first step involves identifying all relevant data sources and extracting the necessary raw data. Since not all data records are equally relevant and they often come in different formats, the second step involves the targeted cleaning, processing, and transformation of the raw data into a uniform, analyzable format.
The overarching goal of this process is to derive valuable, decision-relevant insights from the collected data. In a final step, the transformed data is stored in a central database system or a data warehouse, thereby making it available to users for further reporting and business decisions.
Other important ETL functions:
- Integration: ETL enables the seamless consolidation of data from a wide variety of systems—such as multiple databases, CRM systems, or cloud applications. This creates a unified data foundation that enables cross-departmental evaluations and analyses.
- Data quality: As part of the transformation process, the extracted data is validated, cleaned, and standardized. This ensures that the data is reliable, high-quality, and comparable.
- Automation: Modern ETL tools allow these processes to run regularly and automatically. This saves valuable time, reduces the need for manual intervention, and minimizes the risk of errors.
- Data Delivery: Thanks to ETL, the processed data is made available in the target system promptly and in high quality, so it can be used efficiently for further analyses and decision-making processes.